The global AI arms race is shifting its focus from algorithmic innovation to hardware infrastructure. The industry's systemic reliance on a single vendor has created critical vulnerabilities and placed immense financial pressure on hyperscalers. In a decisive move toward autonomy, Meta is developing proprietary accelerators to radically optimize power consumption and operational costs. This transition signals the dawn of deep vertical integration, where silicon is engineered specifically for the unique demands of neural networks.
The contemporary AI landscape is grappling with a distinct paradox: while model capabilities are expanding at breakneck speed, the cost of sustaining them is becoming prohibitively expensive. For Meta, operating at a scale of billions of users, off-the-shelf solutions from Nvidia are no longer optimal. The answer to this challenge lies in the development of specialized silicon designed to extract maximum performance from every watt consumed and every dollar invested.
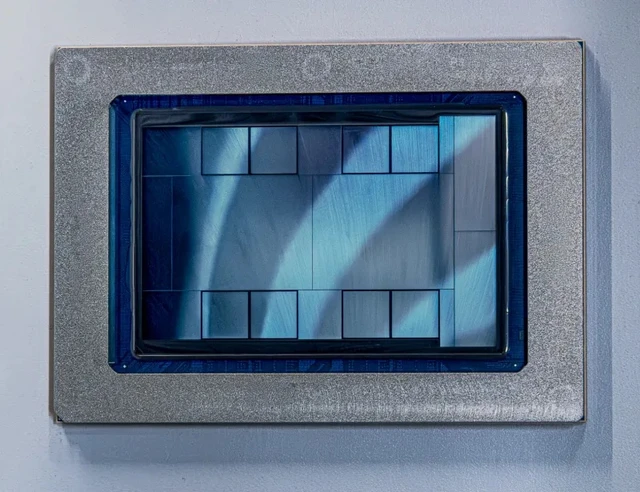
At the heart of this strategy is the MTIA (Meta Training and Inference Accelerator) lineup. Currently, the company is finalizing the testing of its third-generation devices—the MTIA 450, codenamed Arke. Simultaneously, the next phase is underway: the design of the MTIA 500 (Astrid) is nearing completion, with full-scale deployment across data centers expected by the end of next year.
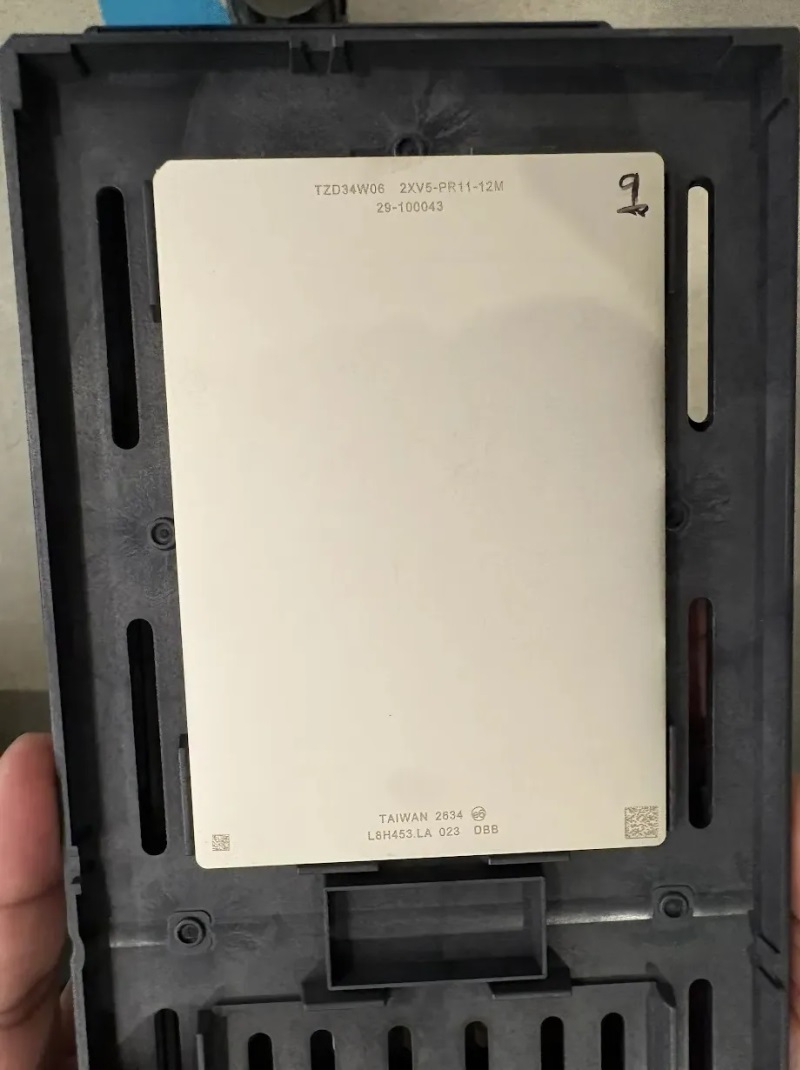
Engineering at this level of complexity cannot happen in isolation; consequently, Meta has forged a strategic alliance with key industry titans. Chip design is handled in collaboration with Broadcom, while fabrication is entrusted to TSMC. This approach allows Meta to focus on workload optimization, delegating the intricacies of lithography and physical implementation to proven partners.
A pivotal role in this process is played by Superintelligence Labs. The engineers architecting future AI models work in lockstep with the hardware developers. This creates a tight feedback loop where the requirements of next-generation neural networks directly dictate the specifications of future chips. The result is a product that outperforms Nvidia’s general-purpose solutions simply because it is purpose-built for Meta’s specific algorithms.
The scale of these ambitions is reflected in the power metrics. Within the coming year, the company intends to deploy accelerator capacity exceeding a total of one gigawatt. In the data center industry, this represents a shift to an entirely different level of computational density, where even marginal optimizations in energy consumption translate into millions of dollars in savings.
Early operational results validate the proof of concept. Test samples received from TSMC demonstrated remarkable precision, with real-world performance deviating from simulations by only 2–3%. Furthermore, the devices successfully handled not only Meta’s internal models but also external algorithms from DeepSeek and Alibaba, confirming the versatility of their approach to inference.
Equally telling is the strategic pivot away from Project Olympus. The original goal was to create a universal chip capable of handling both model training and inference with equal efficiency. However, the economics of gigawatt-scale operations dictate a different reality: the cost of a universal solution proved to be 30% higher than that of a specialized one. At extreme scales, such a discrepancy becomes unacceptable.
Ultimately, Meta is betting on the creation of "workhorses"—devices optimized for general inference utilizing High Bandwidth Memory (HBM). These chips do not aim for record-breaking latency in niche segments; instead, they provide the necessary stability and economic efficiency, transforming AI infrastructure from a cost center into a high-yield asset.
 The Commercial Debut of the Googlebook Ecosystem